Meet the prototab DE browser workbench.
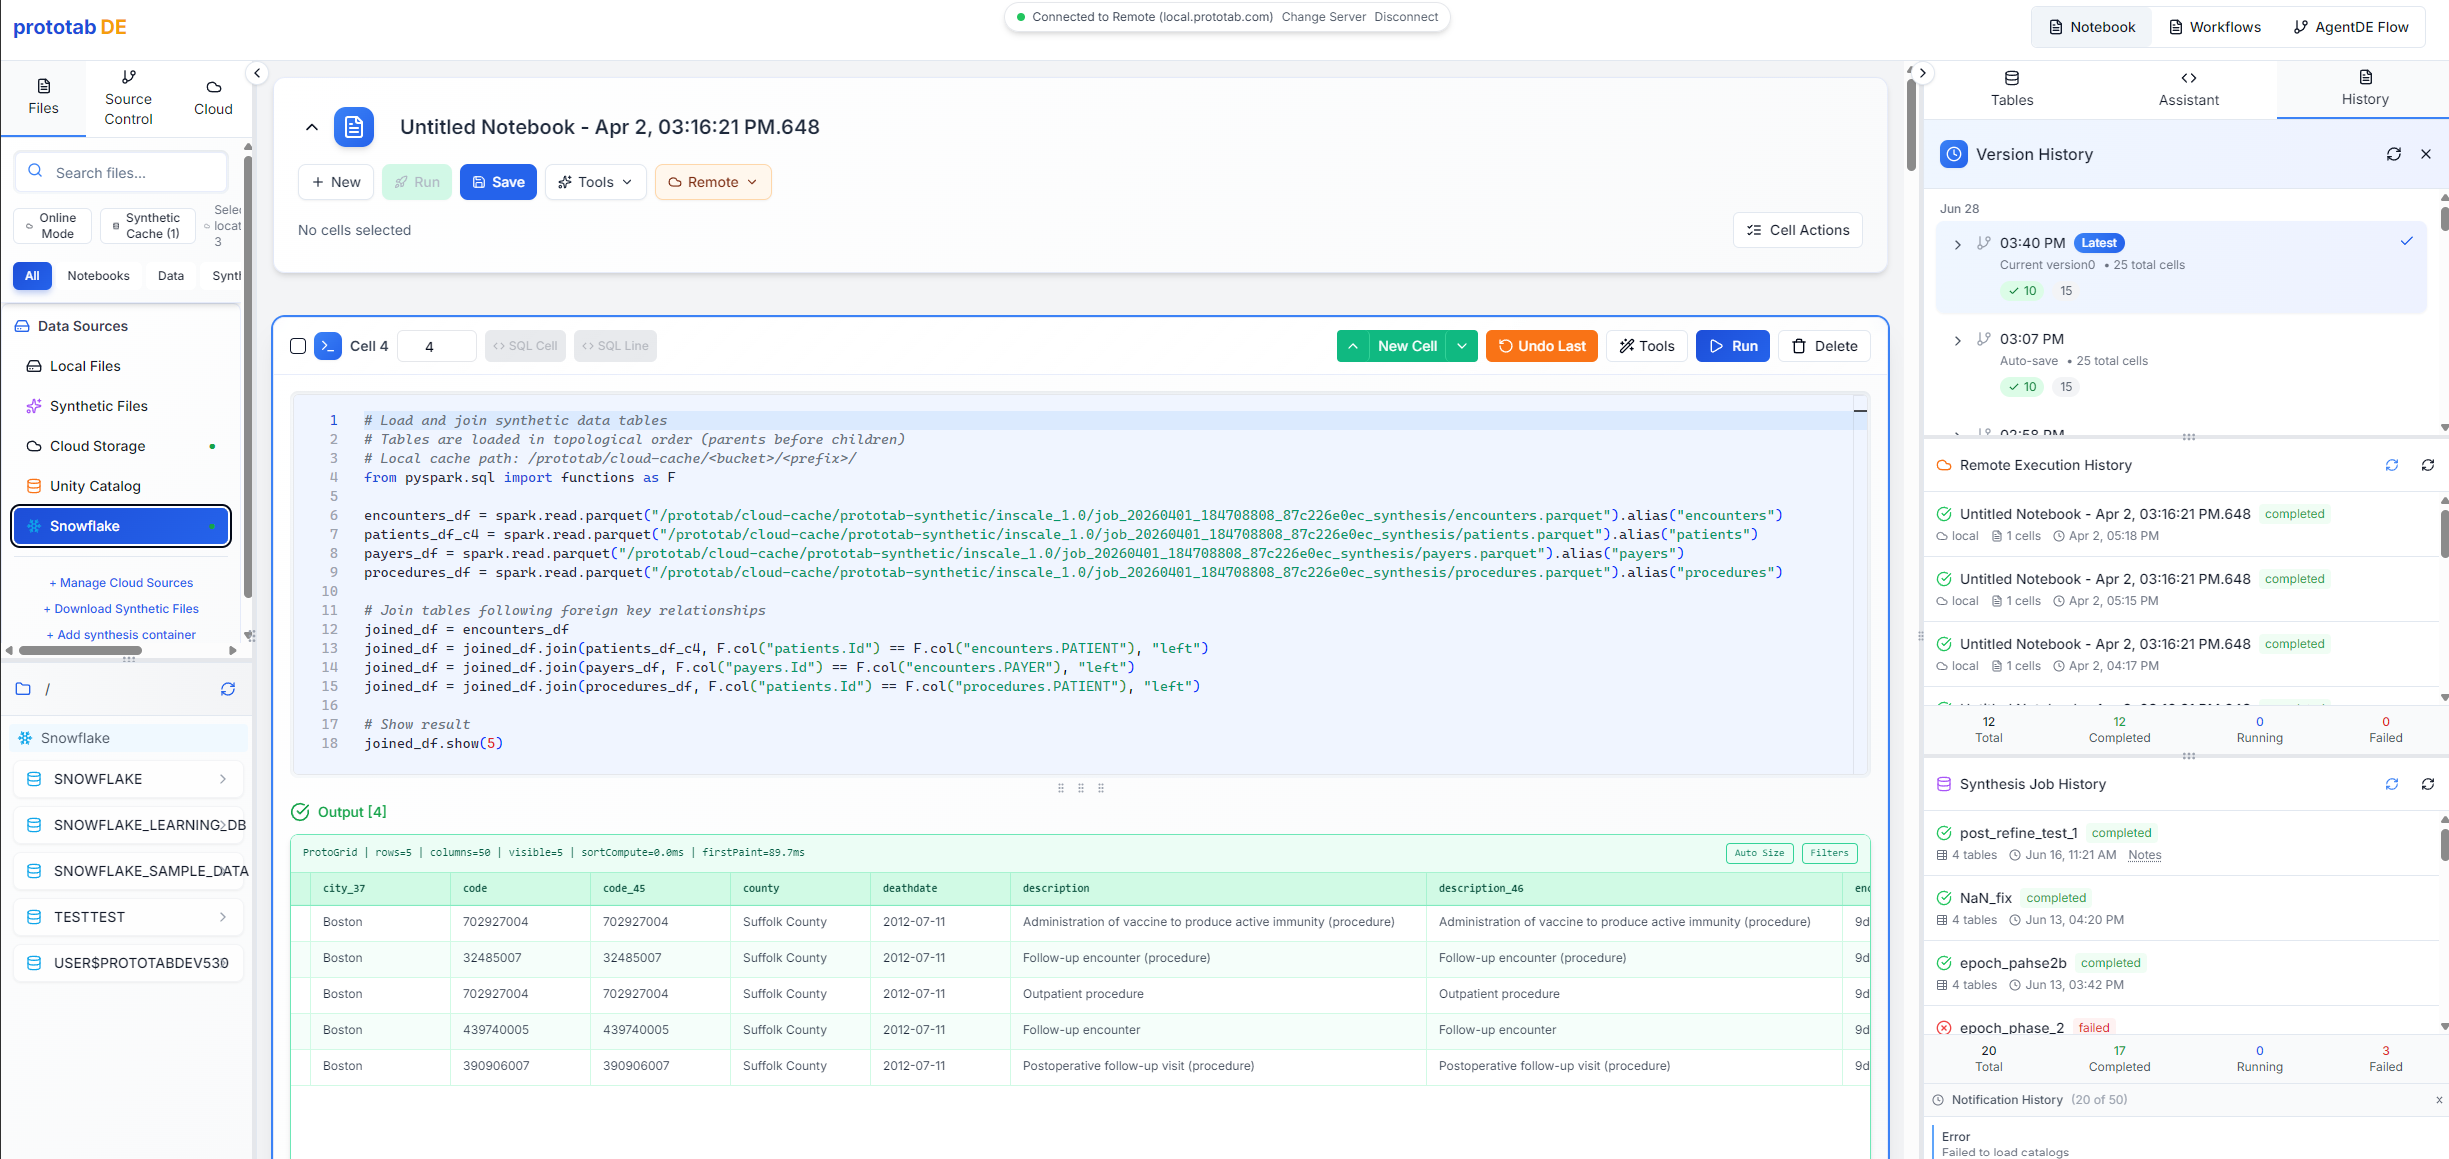
PySpark compliant notebook without the bloated Spark runtime. No sensitive data downloads. Our Dynathesis™ physics-based engine automatically generates join-preserving synthetic data directly to your workstation, letting you iterate and debug locally. When the logic is ready, run your code against real data in Databricks with one click, while Canvient™ keeps real results out of the browser. The cloud meter only runs when the work requires it.
A PySpark and SQL notebook that runs on your own computers.
prototab DE makes synthetic data on demand, so your team builds and tests pipelines locally, at no cloud cost, and only reaches for Databricks or Snowflake when there's real work to run. Same code, same dialects. The cloud bill stops paying for the practice runs.
In the browser, on the engineer's own machine. No cluster to spin up, works offline.
Privacy-safe stand-in data that keeps your joins, so iteration does not need real records.
Spark, Snowflake, Databricks, DuckDB, Hive. What you build locally is what you run in the cloud.
Generate. Develop locally. Deploy when ready.
Integrated with Databricks, Unity Catalog, Snowflake, and cloud storage. Built by data engineers, for data engineers.
One click produces synthetic data that keeps the structure, joins, and statistical shape of your real data. Fully automated. No tuning, no PhD required.
Engineers prototype, debug, and test on their own workstations using synthetic data. No cloud compute. PySpark and SQL. Works offline.
When the code is validated, run it remotely in Databricks, Snowflake, or a prototab container against real data. Results return through Canvient™, so real data never lands in the browser.
Early exploration and testing run on the engineer's own machine with synthetic data, so cloud compute sits idle until you actually need it. Savings start on day one. Synthetic data is local, so your team keeps working offline. No internet, no VPN. The airplane is a productive place again.
We don't compete with Databricks and Snowflake. They're more powerful and more expensive. Save them for when you really need them. What we add is choice and control over when the meter runs.
Privacy does not cut the cloud bill. Workload displacement does.
Synthetic data makes real data replacement safe. The integrated workbench makes workload displacement practical. The avoided cloud workload is the OpEx reduction.
Each synthesis job produces evidence: PII remediation, privacy-risk indicators, utility metrics, join preservation, and audit-ready certificate details.
Safe synthetic data stands in for production data during iterative work that does not require real records or production-adjacent access.
Exploration, development, testing, and debugging move into a local workbench instead of running every loop through a metered cloud platform.
Cloud platforms stay in place for production truth. prototab DE reduces avoidable usage where the cloud meter should not have to run.
The CFO sees avoided spend. The CISO sees reduced exposure. The CIO sees a customer-owned deployment.
This is not a rip-and-replace story. prototab DE augments Databricks, Snowflake, cloud data lakes, and regulated data platforms by moving the work that does not need real data into a safer, lower-cost place.
"You watched the bill climb every quarter and couldn't say exactly why."
Fixed price, unlimited use, and a calculator-friendly savings mechanism.
"Your data can't leave the building, so half the modern tooling is off the table."
The cost case only works because the synthetic data is serious enough to replace real data for non-production work.
"Every platform takes a quarter to stand up. You want one that's done on day one."
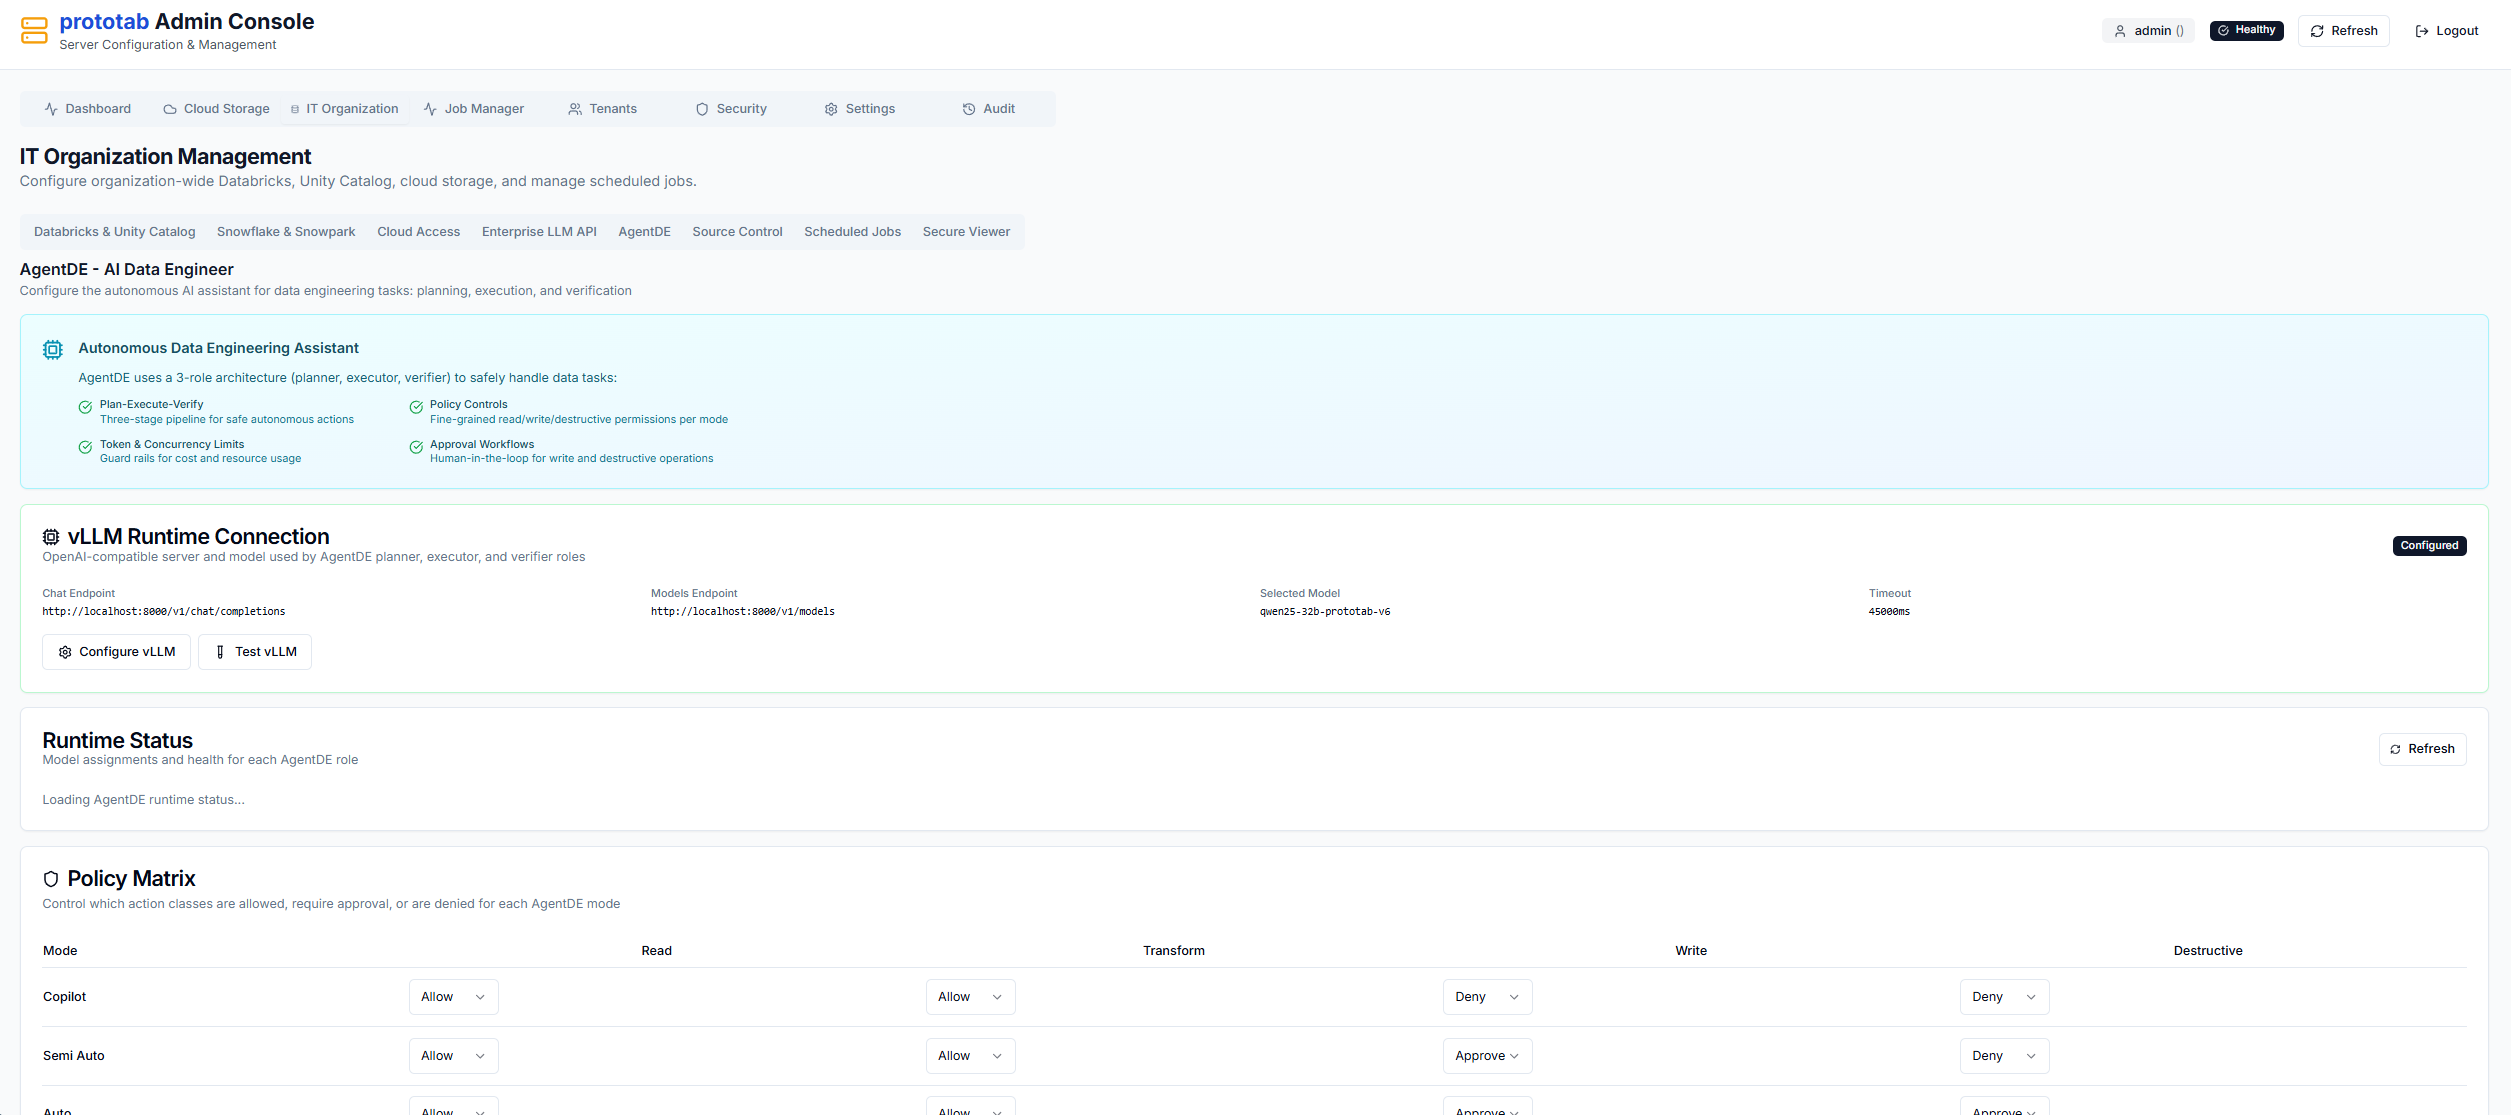
A customer-deployed workbench with admin controls, synthetic generation, notebooks, no-code workflows, and internal AI.
A generator alone is another line item. A workbench changes where the work happens.
The market established synthetic data for privacy. We use that trust foundation to open a second value tap: safe, lower-cost iteration.
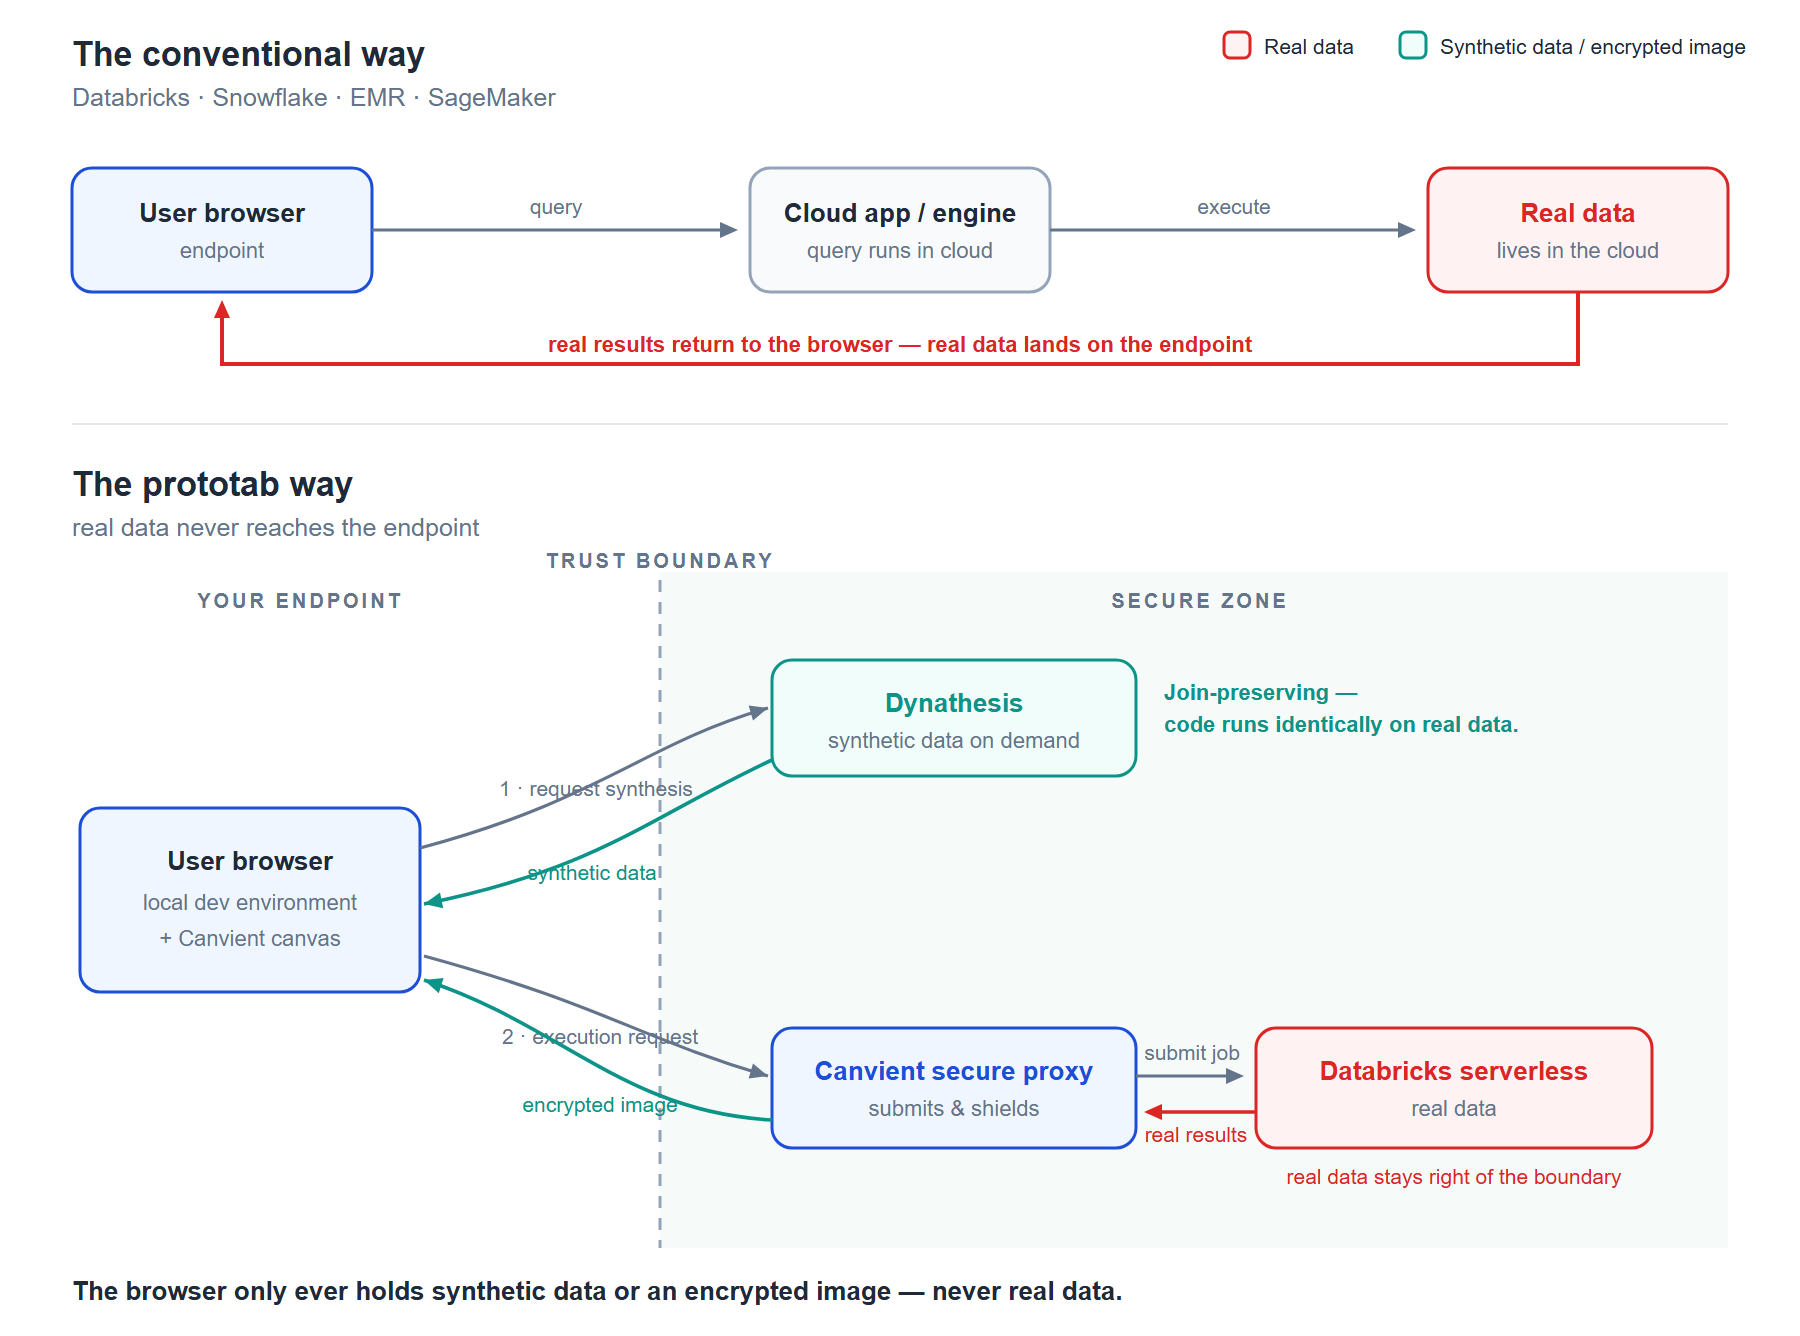
The browser should never become a data endpoint.
Conventional cloud data apps send real query results back to the user's browser. prototab DE changes the flow: the browser works with synthetic data for iteration, and when real execution is required, Canvient™ shields real results so real data stays on the right side of the trust boundary.
Browser-based data tools normalize real data landing on the endpoint. That creates exposure through browser extensions, developer tools, screen capture, cached memory, and local workstation policy gaps.
Cloud costs are eroding your margins. You already know this.
Cloud cost tools monitor spending after it happens. They ration and audit, they don't reduce costs. We don't help you forecast better. We eliminate the variance.
You've been trained to think this is what data engineering costs. It isn't. It's what it costs when your vendor succeeds by you using more.
Convert your second-largest expense from an unpredictable variable into a known fixed cost.
How much? No obfuscation. No "contact sales."
We don't need lock-in to prove a short payback. So the price is simple.
One price. Unlimited users. Unlimited use. Regain the freedom of choice. It's time for an alternative to lock-in.
prototab DE pays for itself in the first 30 to 60 days.
Most enterprises spend 27% of their cloud data-platform budget on dev and test. We replace that line item with a flat $50K. Prove the payback in billing cycles, not transformation programs.
Sources: Gartner public cloud forecast (21.5% YoY); Flexera State of the Cloud (27% dev/test allocation, ±15% forecast variance); Atlassian Developer Experience Report (8+ hrs/week lost to inefficiencies); Statista IT Outsourcing Survey and HireWithNear 2026 benchmarks (offshore data engineer 50-75% savings).
It runs in the browser. Here's the stack that makes that real.
No installation, no cluster, no server round trip. Credibility for the part that sounds too good to be true.
Python and SQL engines run in the browser at close to native speed, inside the browser sandbox.
A fast analytical SQL engine runs locally. Columnar storage and vectorized execution handle large local files.
Write Spark, Snowflake, Databricks, DuckDB, or Hive SQL. The translation layer, built on SQLGlot, converts between them, including CTEs and window functions.
Files up to about 20GB live in the browser's OPFS. Persistent, local, and available offline.
Jobs run in a background service worker, so the interface stays responsive while work happens.
A local code assistant routed through your own enterprise LLM provider. No external data leakage.
Enterprise software without the hosted-SaaS tax.
We kept the modern UI, simple licensing, and fast deployment. We removed the hosted data plane, telemetry, usage metering, vendor-side workflow logs, and support dependency.
Source data, synthetic data, prompts, notebooks, job logs, outputs, and usage history stay inside your environment.
We do not monitor your instance, track users, collect activity analytics, or maintain remote access.
Your deployment is secured by your policies, identity provider, infrastructure controls, and change-management rules.
Our hosted footprint is customer-agnostic app distribution and billing. Our breach should not become yours.
This is not marketing language. This is architecture.
Stripe stores your purchasing information. We store nothing about your usage. Your data is yours. We're not watching.
If software is truly turnkey, support should not be a second product.
prototab DE is built to be installed, operated, and evaluated by your team. Have a question? Email or call us. Otherwise, we are not in your environment.
prototab is a platform, not a single tool.
prototab DE is the data engineering surface. The platform extends to agentic authoring and local AI runtimes.
Data Engineering
The PySpark and SQL notebook with Synthetic Data on Demand. Local-first development, remote execution against real data, Databricks and Snowflake integration.
$50,000 / year flat
Agentic Data Engineering
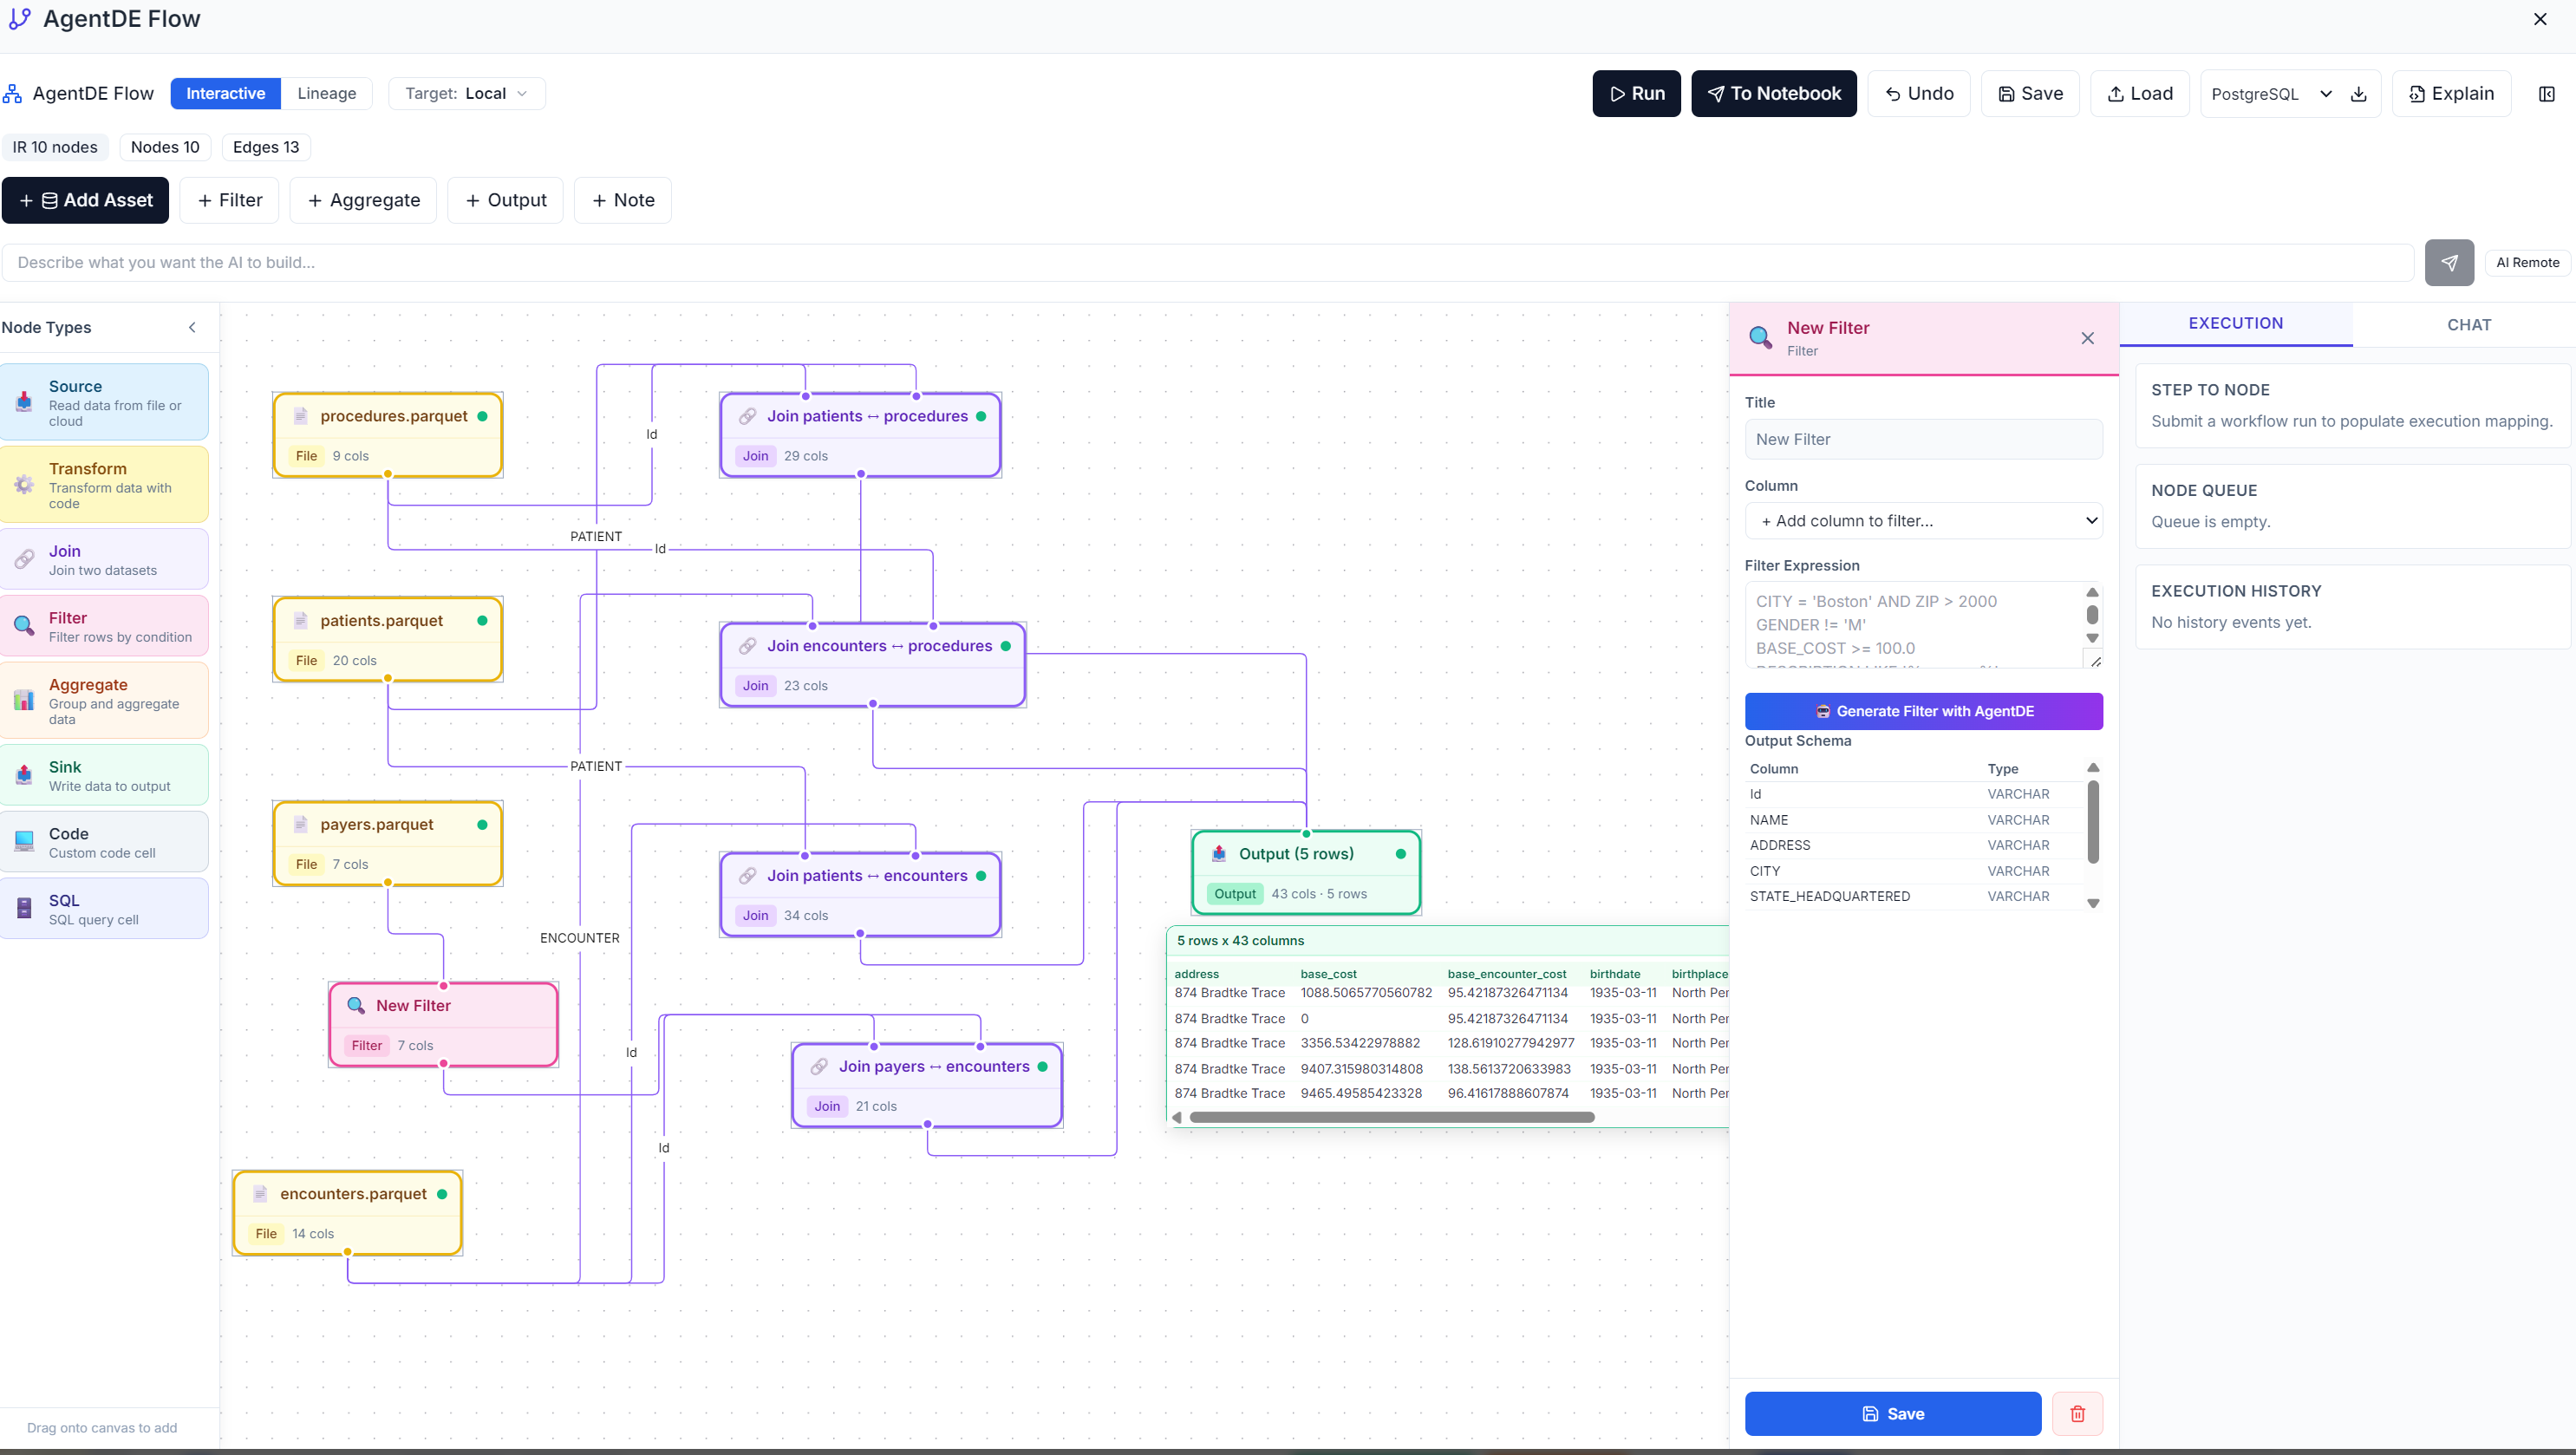
The agentic authoring layer. Natural-language task intake produces executable plans you review and approve. Author once with AI, run repeatedly without AI. Successful traces compile into deterministic workflows.
Flow + Notebook, co-equal surfaces
Local-first AI workspace
A browser-native local AI runtime. Run approved local models on CPU, Vulkan, or CUDA, with no remote API by default. Managed runtimes, integrated tools, enterprise-grade controls.
Local intelligence, no setup tax
DE · EE · TE · SE · ME, each sub-brand addresses a different stage of the data lifecycle. All run on the same execution and privacy posture.
Start your deployment.
$50,000/year, unlimited users and use, customer-deployed. PO and net-30 invoicing, no card required. You're provisioned after a brief review; the first invoice arrives about 30 days later. We are a privacy-first company. Your PO and buyer information is stored securely in Stripe. We store no customer data, ever.
Request a demo.
See prototab DE and AgentDE Flow on a live walkthrough. Tell us how to reach you and we'll get it scheduled.
Move the iterative work that does not belong on the cloud meter. Replace real data where real data is not required. Prove the payback in billing cycles, not transformation programs.
Why doesn't everyone price it this way? Because the companies selling you cloud compute make more when you use more. We don't sell compute. We sell you the tool, once, at a price you can read.